TL;DR
A PostgreSQL GiST index is a generalized, extensible index structure built for data that does not fit B-tree's strict ordering model — range types, geometric and spatial data, full-text search, nearest-neighbor lookups, and exclusion constraints. If your queries use operators like &&, <->, or @>, or you need EXCLUDE USING GIST, GiST is usually the right tool. For simple equality or range scans on scalars, stick with B-tree.
Introduction
If you have ever created an index in PostgreSQL without specifying a method, you got a B-tree — and for most workloads, that is the correct default. But a PostgreSQL GiST index exists for a reason: plenty of useful queries cannot be answered efficiently by a structure that only understands "less than, equal, greater than" on sortable values.
Consider these common questions:
- Which scheduled meetings overlap with 2:00–3:00 PM on Monday?
- Which delivery drivers are currently inside a given service area?
- Which rows in a log table contain a string similar to "Kubernets"?
None of these are simple equality or range scans on a sortable column. A B-tree index on a tstzrange column, for example, will not help with the overlap operator &&. This is where the Generalized Search Tree — GiST — earns its place in your schema.
In this guide you will learn what a GiST index actually is, the main use cases where it beats B-tree and GIN, how to create and verify one, and the trade-offs to watch out for. All examples are standard PostgreSQL syntax you can run in any recent version, whether you use psql or a GUI client like DBO Studio.
What Is a GiST Index in PostgreSQL?

GiST stores bounding predicates per subtree; B-tree stores strictly ordered scalar keys.
Generalized Search Tree explained in plain terms
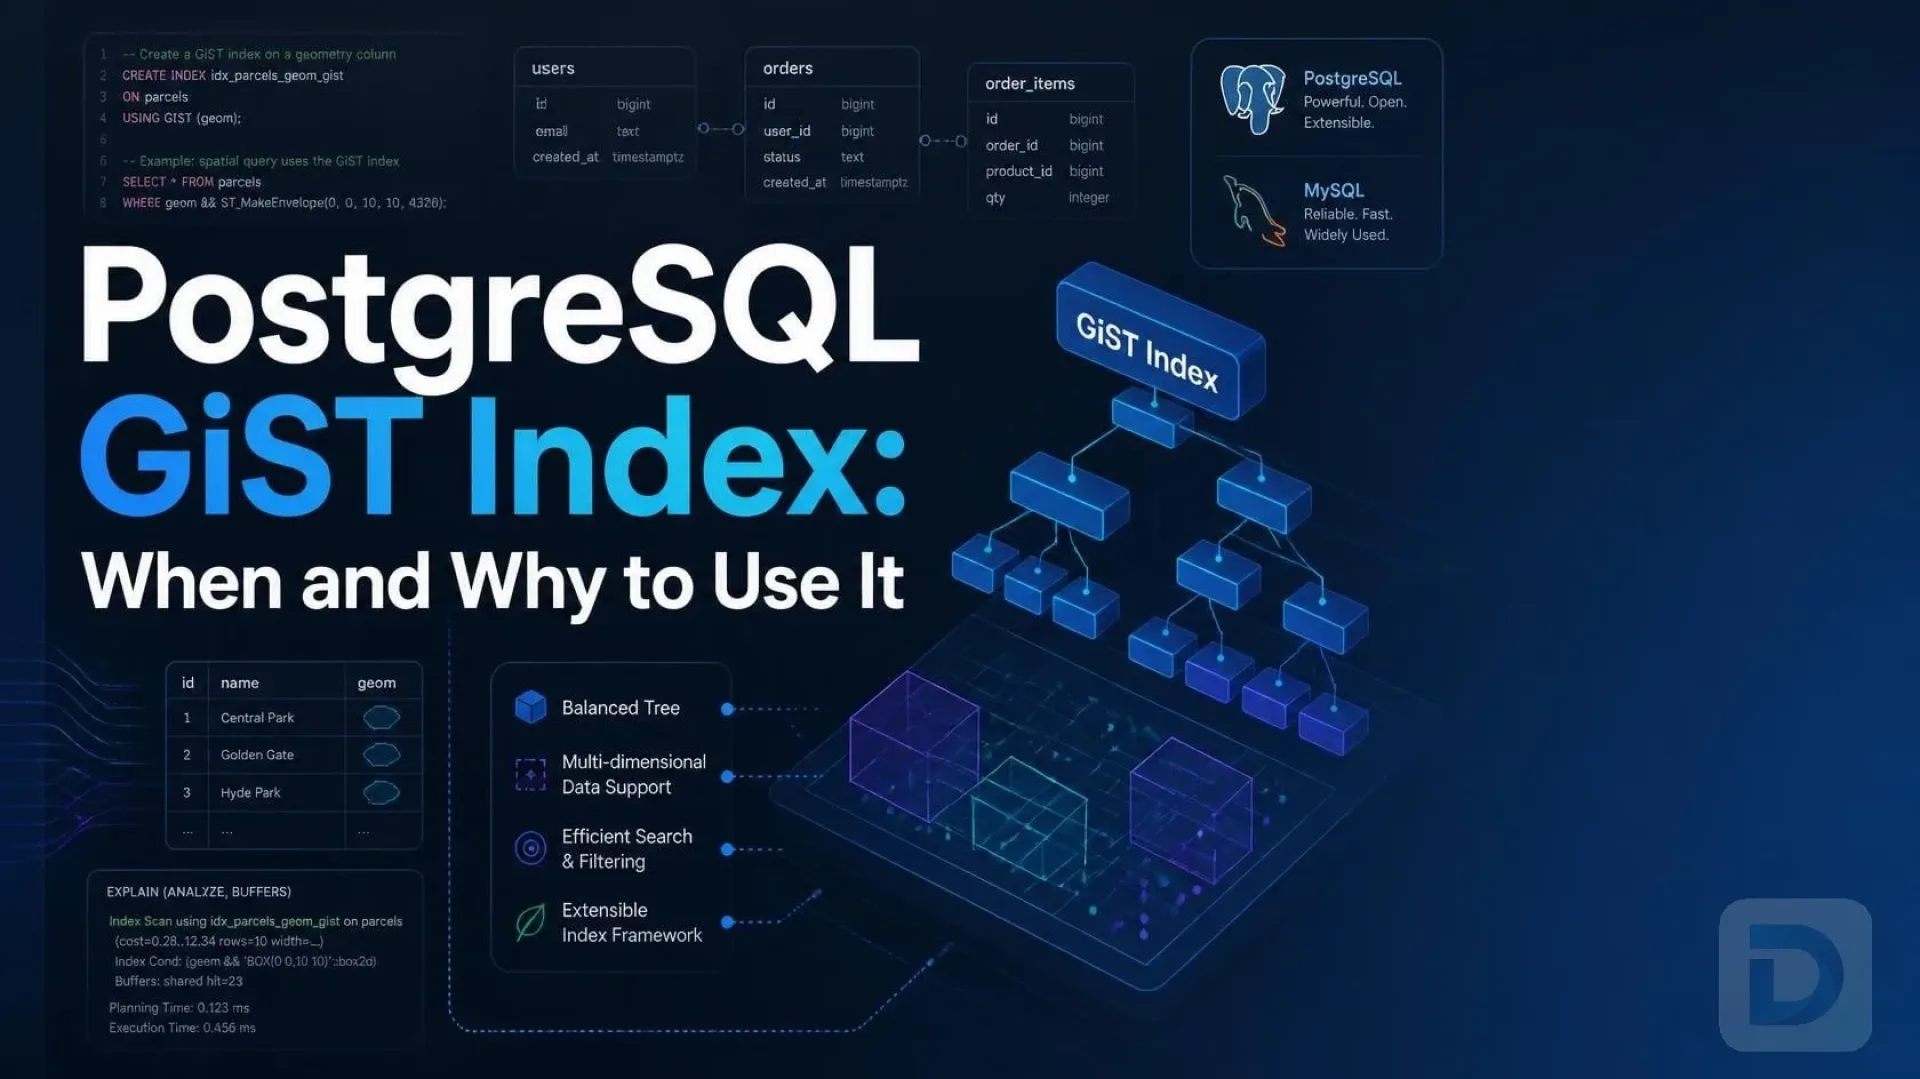
GiST stands for Generalized Search Tree. It is not a single index algorithm but a framework — a balanced tree template that lets PostgreSQL plug in domain-specific logic. Each node in a GiST tree stores a predicate that summarizes everything beneath it, and the plugin (called an operator class) defines how to test, combine, and split those predicates.
For spatial data, that predicate is typically a bounding box: "everything below this node lies within this rectangle." For range types, it is an enclosing interval. The tree does not need your data to be linearly ordered — it only needs to know how to ask, "could the answer possibly live in this subtree?"
That single property is why GiST supports such a wide variety of queries: it delegates all the domain-specific work to the operator class.
How GiST differs structurally from B-tree and GIN
- B-tree stores sorted scalar keys. It answers
<,<=,=,>=,>andLIKE 'prefix%'efficiently, and it is the only access method that fully supports ordering and index-only scans on arbitrary columns. - GIN (Generalized Inverted Index) stores a mapping from small keys (words, trigrams, array elements) to lists of rows. It shines for containment queries on
jsonb, arrays, and full-text search, but each row can appear in many posting lists, and GIN updates are comparatively expensive. - GiST stores one summary predicate per entry per row. It is more flexible in the operators it can accelerate, often faster to update than GIN, but usually slower to search for exact containment than a well-populated GIN.
Operator classes: what makes GiST extensible
The behavior of a GiST index is defined by the operator class attached to each indexed column. For example:
range_ops— for range types (tstzrange,int4range,numrange, …)gist_geometry_ops— for PostGIS geometry and geographygist_trgm_ops— for similarity search on text (via thepg_trgmextension)inet_ops— forinetandcidrnetwork containment
Extensions like PostGIS exist largely because GiST lets them plug in custom indexing logic without touching the core engine. If you want to see what operator classes are available for a type, query pg_amop and pg_opclass, or simply check the official GiST documentation.
When to Use a GiST Index: The Main Use Cases
Range types: tstzrange, int4range, and scheduling queries
Range types are the most common everyday reason to reach for GiST. Suppose you store meeting reservations as time ranges:
CREATE TABLE bookings (
    id          bigint GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
    room_id     int NOT NULL,
    during      tstzrange NOT NULL
);

CREATE INDEX ON bookings USING gist (during);
Now queries that B-tree cannot accelerate become index-backed:
-- Find all bookings that overlap Monday 2:00–3:00 PM
SELECT * FROM bookings
WHERE during && '[2025-06-02 14:00, 2025-06-02 15:00)';

-- Find bookings entirely contained in a window
SELECT * FROM bookings
WHERE during <@ '[2025-06-02 09:00, 2025-06-02 18:00)';
Operators accelerated by the range_ops GiST class include && (overlap), @> and <@ (contains / contained by), and << / >> (strictly left / right of). This is the canonical postgres range index pattern.
Geometric and spatial data with PostGIS
PostGIS is the flagship GiST consumer. A spatial index on geometry data lets you answer "what is inside this polygon" and "what intersects this area" without scanning every row:
CREATE INDEX ON restaurants USING gist (location);
Without a GiST index, a spatial filter degenerates into a full table scan with expensive geometry math per row. With one, PostgreSQL quickly prunes the search space using bounding boxes, then rechecks the exact predicate. If you work with maps, geofences, or GPS traces, the GiST-based PostGIS index is non-negotiable.
Full-text search with trigram and tsvector
GiST can also power text search. With the pg_trgm extension, a gist_trgm_ops index supports both LIKE/ILIKE with wildcards anywhere in the string and similarity matching:
CREATE EXTENSION IF NOT EXISTS pg_trgm;

CREATE INDEX ON logs USING gist (message gist_trgm_ops);

-- Similarity search for typo-tolerant matching
SELECT * FROM logs
WHERE message % 'Kubernetes deploy failed'
ORDER BY message <-> 'Kubernetes deploy failed'
LIMIT 10;
For tsvector full-text search, both GIN and GiST work. GIN is generally preferred for read-heavy exact-match search; GiST can be a better fit when the indexed column is updated frequently, since GIN index maintenance is heavier per write. The trade-off is typically slower searches on GiST — measure both against your real workload rather than assuming.
Exclusion constraints: preventing overlapping bookings
Exclusion constraints are a uniquely powerful feature enabled by GiST — there is no B-tree equivalent. They enforce "no two rows may satisfy a given predicate," which generalizes uniqueness:
CREATE EXTENSION IF NOT EXISTS btree_gist;

ALTER TABLE bookings
ADD CONSTRAINT no_double_booking
EXCLUDE USING gist (
    room_id WITH =,
    during  WITH &&
);
This constraint rejects any insert where the same room has a booking whose time range overlaps the new one. Note that room_id WITH = requires the btree_gist extension, because plain integers are not natively indexable by GiST — more on that below.
Nearest-neighbor queries with ORDER BY <->
GiST supports distance operators that enable K-nearest-neighbor searches directly in the index. With a spatial index, "find the five closest coffee shops" becomes:
SELECT name, location
FROM coffee_shops
ORDER BY location <-> point(40.7128, -74.0060)
LIMIT 5;
The <-> operator works with geometric types and PostGIS geometries (and pg_trgm uses it for string distance). PostgreSQL walks the GiST tree in proximity order, so it can stop after finding the first k results instead of sorting the entire table.
GiST vs B-tree vs GIN vs SP-GiST

Which PostgreSQL index access method fits which workload.
PostgreSQL ships several index access methods, and choosing between them is a recurring design decision. Here is how they compare on the dimensions that matter:
| Dimension | GiST | B-tree | GIN | SP-GiST |
|---|---|---|---|---|
| Best-fit data | Ranges, geometry, text, networks | Scalars, dates, sortable values | jsonb, arrays, tsvector | Points, prefixes, quadtrees |
| Key operators | &&, @>, <->, << | <, =, >, LIKE 'abc%' | @>, ?, @@ | <<, ^@ (varies) |
| Exclusion constraints | Yes | No (unique only) | No | No |
| Nearest-neighbor search | Yes | No | No | Limited |
| Typical search speed | Good | Excellent for scalars | Excellent for containment | Varies by opclass |
| Update overhead | Moderate | Low | High | Varies |
A few practical notes:
- Postgres GiST vs B-tree is not a performance contest on the same workload — they simply answer different query shapes. If a B-tree can serve your predicate, it usually should.
- GiST vs GIN is a genuine trade-off for full-text and containment workloads: GIN searches faster, GiST updates faster. Test with your write/read ratio.
- SP-GiST covers space-partitioned structures (quadtrees, radix trees) and is worth a look for point or prefix data, but GiST is the more general choice.
See the official index types overview for the complete picture.
How to Create and Test a GiST Index
Basic CREATE INDEX USING GIST syntax
The general form is:
CREATE INDEX [CONCURRENTLY] [index_name]
ON table_name USING gist (column [opclass] [, ...]);
For example, a network containment index:
CREATE INDEX ON firewall_rules USING gist (source_cidr inet_ops);

SELECT * FROM firewall_rules
WHERE source_cidr && '192.168.1.0/24'::inet;
Use CONCURRENTLY on production tables to avoid locking writers during the build — at the cost of a longer build time and the need for a second pass if it fails.
Installing btree_gist for scalar types
GiST has no native operator classes for plain int, text, or timestamp columns. If you need them in a GiST index — almost always for multi-column exclusion constraints — enable the btree_gist extension:
CREATE EXTENSION IF NOT EXISTS btree_gist;
It provides GiST equivalents of the standard B-tree operators. Do not use it as a general-purpose substitute for B-tree indexes; its search performance on scalars is generally worse. Reserve it for constraints that mix scalar equality with GiST-native predicates.
Verifying usage with EXPLAIN ANALYZE
Never assume an index is used — verify it:
EXPLAIN ANALYZE
SELECT * FROM bookings
WHERE during && '[2025-06-02 14:00, 2025-06-02 15:00)';
Look for a plan node such as Bitmap Index Scan on bookings_during_idx, or an Index Scan for nearest-neighbor queries. If you see Seq Scan, common causes are a missing operator class, a predicate the index does not cover, or a table small enough that the planner correctly prefers a scan. A GUI like DBO Studio makes it easy to run EXPLAIN ANALYZE and inspect plans without memorizing plan-tree output.
Common Pitfalls and Performance Considerations
Lossy pages and recheck costs
GiST index entries can be lossy: a parent entry may say "the answer might be in this subtree" when it is not. PostgreSQL handles this by rechecking the original predicate against the actual row after fetching it. For highly selective spatial predicates, the recheck cost can be significant. There is no pg_trgm-style exact-vs-lossy toggle you control directly; the effect shows up as time spent in the plan node after index fetch. Keep statistics fresh with ANALYZE so the planner estimates recheck costs realistically.
Slow writes on high-churn tables
Every index adds write overhead, and GiST is no exception. Inserts and updates on heavily indexed tables will be slower than on a bare table, and a bloated GiST index degrades search performance over time. If write latency grows after adding GiST indexes:
- Monitor index size with
pg_relation_size(). - Rebuild with
REINDEX INDEX CONCURRENTLYwhen bloat accumulates. - Consider partial GiST indexes (e.g., only index future bookings:
WHERE during @> now()).
When GiST is the wrong choice
Choose something else when:
- Plain equality or range scans on sortable columns → B-tree.
- Read-mostly
jsonbor array containment → GIN. - Prefix or point lookups → evaluate SP-GiST.
- Tiny tables → often no index at all; the planner will ignore it anyway.
The goal of index design is not to maximize indexes — it is to match access methods to your actual query predicates.
FAQ
A GiST index accelerates queries that B-tree cannot express: overlap and containment on range types, geometric and spatial predicates, trigram similarity search, network containment on inet/cidr, nearest-neighbor ordering, and exclusion constraints. It is a generalized, extensible tree structure defined by per-type operator classes.
Not on B-tree's home turf. For equality and range predicates on sortable scalars, B-tree is generally faster and fully supports ordering. GiST wins only on operators B-tree does not implement at all, where the alternative is a sequential scan.
Choose GIN for read-heavy containment workloads — jsonb @>, array operators, and exact full-text matching — where GIN's search speed dominates. Choose GiST when writes are frequent, when you need distance operators or exclusion constraints, or when your data type only has a GiST operator class.
Not natively. GiST has no built-in operator classes for scalar types like int or text. The btree_gist extension adds them, mainly to enable multi-column exclusion constraints, but a regular B-tree index remains the better choice for pure equality lookups.
Run EXPLAIN (ANALYZE, BUFFERS) on your query and look for an index scan node referencing the GiST index. If you see a sequential scan, verify the predicate uses an operator the index's operator class supports, that statistics are current, and that the table is large enough for an index to pay off.
Yes, like any index, it adds maintenance cost per write — typically moderate, and generally lighter per-update than GIN. On high-churn tables, monitor for bloat and rebuild with REINDEX INDEX CONCURRENTLY when needed. Partial indexes can reduce overhead by indexing only the rows you actually query.
EXCLUDE USING GIST enforces that no two rows satisfy a predicate you define — for example, room_id WITH =, during WITH && prevents two bookings for the same room from overlapping in time. The GiST index is what lets PostgreSQL check this constraint efficiently on every insert and update.
Yes. GiST supports distance operators such as <->, so ORDER BY column <-> point LIMIT k returns the k nearest rows without sorting the whole table. This works for geometric types, PostGIS geometries, and (via pg_trgm) text similarity.
Key Takeaways
- GiST is the generalist index: it powers range overlap, spatial queries, trigram search, network containment, and exclusion constraints — predicates B-tree cannot express.
- Exclusion constraints require GiST (with
btree_gistfor scalar columns); there is no B-tree equivalent. - GiST vs GIN is a read/write trade-off for text and containment workloads: GIN searches faster, GiST updates faster.
- Keep B-tree as your default for equality and range scans on sortable columns.
- Always verify with
EXPLAIN ANALYZE— an unused index is pure write overhead.
Conclusion
Use this quick checklist when deciding whether a GiST index fits:
- Does your predicate use
&&,<@,@>,<->, or a spatial operator? → GiST candidate. - Do you need an exclusion constraint? → GiST, required.
- Is the workload write-heavy full-text or containment search? → Benchmark GiST vs GIN.
- Is it plain equality or a sortable range scan? → B-tree.
Once you know when and why to use a PostgreSQL GiST index, the "how" is one statement — CREATE INDEX USING gist — and a plan check to confirm it is being used. If you want a fast, cross-platform GUI for experimenting with indexes, inspecting query plans, and managing PostgreSQL alongside MySQL, SQLite, and SQL Server, download DBO Studio and see your index usage at a glance.
For deeper reference material, consult the PostgreSQL GiST documentation and the CREATE INDEX reference.
About the author

Founder & Lead Developer at DBO Studio
Full-stack developer and creator of DBO Studio, a modern database management tool. Passionate about PostgreSQL, MySQL, SQLite, database performance, developer productivity, and building tools that simplify database workflows.
Try this in DBO Studio
Explore PostgreSQL workflows visually in DBO Studio — schemas, queries, and plans in one place.
Our newsletter
Subscribe to DBO Studio’s newsletter for exclusive tutorials, tips & product updatesRelated posts